An update on vote efficiency in Quebec · ↗ www.thewrit.ca
Quebec held an election two days ago, which saw the province’s sovereigntist Parti Québécois emerge victorious with 59 of 127 seats, five short of the 64 required for a majority. Meanwhile, the ruling CAQ collapsed from winning 90 of 125 seats (72%) in the 2022 election to zero this time around.
I wrote a post in April about vote (in)efficiency in Quebec, pointing out that the Parti Québécois won just 6 of 110 seats with 30% of the vote in the province’s 1973 election but could now plausibly win a majority with the same level of popular support.
What ended up happening Monday was that the Parti Québécois got 28% of the vote and carried 59 seats, five seats short of a majority. It was the lowest vote share ever for a winning party in the province; the previous low was the Parti Québécois’s 32% in 2012. It is also one of the lowest vote shares for a party forming government in Canadian history.
Part of the explanation is that this was an unusually fragmented election, with five viable parties splitting almost the entire vote. The second-place Liberals took just 24%, the Conservatives 21%, the CAQ 13%, and Québec solidaire 12%.
Éric Grenier from The Writ (also co-host of the excellent polling-focused podcast Les chiffres) points out that this was the first time in Canadian history, across all federal and provincial elections, that no party was able to capture at least 30% of the vote.
…Jev for social media fabulism · ↗ www.conspirator0.com
Jev is a new type of AI classifier ingesting natural language and outputting probabilities of three types: choices, scores, and yes/no. It promises similar performance to frontier LLMs but roughly two orders of magnitude faster and cheaper.
(Jev has been the talk of the town since it dropped on September 15, but I was travelling in the North when it came out. I first heard about it when a friend texted me, “oh they’re not talking about Jev in the Canadian Arctic?” I assumed “Jev” was the perfect joke name for whatever new thing in AI everyone was suddenly talking about, until I Googled it and discovered that Jev was, in fact, the new thing in AI everyone was suddenly talking about.)
Conspirador Norteño is a fun follow, an anonymous account sniffing out inauthentic social media accounts and bot networks. They used to focus on Twitter, but since that website shut off API access, they have focused on Bluesky. Not long ago, they posted their particular use case for Jev: semi-automated identification of contradictory biographical statements from dubious Bluesky accounts.
Sensational accounts on social media frequently lie about their personal and professional lives (Reddit story accounts are perhaps the most extreme example of this phenomenon), and what Conspirador did was pull posts from a list of Bluesky accounts, use Jev to classify whether they contained biographical claims, then use Jev again to compare claims pairwise to determine if they contradicted each other. For example, inconsistencies in work history or claiming to have good knees in one post and bad knees in another.
…WeWorm · ↗ calif.io
The WeWorm exploit dropped by Calif Research about a month ago is pretty nuts: the first zero-click worm for WeChat, capable of gaining full control over a user’s WeChat account and subsequently attacking everyone on that user’s contact list.
For those of you who have never heard of WeChat, it is China’s “everything app”: used for payments, messaging, and social media. It is also deeply embedded in China’s censorship and surveillance infrastructure. As such, gaining control over a user’s WeChat account gives an attacker a lot of power.
The exploit discovered by Calif researchers is about as bad as it gets. For the attack to work, the target must be on the “friend list” of the attacker, but the target is not required to answer the malicious call or interact with it in any way. While hanging up on the call blocks the exploit, an attacker can simply call again at a time when the user is unlikely to be awake. When account control is achieved, the compromised account can begin targeting all the users on the victim’s friend list. The attack can potentially be chained with other exploits to gain complete control over a victim’s iPhone or Android device.
Calif said they developed this attack with AI assistance, and they only published it after confirming that Tencent, the creator of WeChat, had fixed the exploit. There is no evidence that this exploit was used in the wild. But Calif says its AI found the bug and helped write the first remote-code-execution exploit in about two days, with the worm taking another week to build. That speed speaks to the new era of online security in the age of incredibly capable AI coding tools.
…Bring on the spending caps · ↗ simonwillison.net
Cloud provider bills should not come with unlimited downside
Simon Willison has a good post arguing for hard budget caps by default on pay-for-usage services and APIs. Large compute providers like AWS and Google Cloud have traditionally used soft caps, i.e., you receive an email at 2 AM warning that your spending has reached 80% of your limit, and then you wake up to a $2,000 bill after some bot finds your demo or (more optimistically) it goes viral.
Thankfully, both cloud providers have recently introduced hard spending caps. For disposable projects, demos, experiments, etc., I’ve always liked the prepaid-credit and per-key spending caps of services like OpenRouter, but these changes make the big cloud providers more viable for these use cases.
There’s a discussion of the article on Hacker News, with commenter motionlessveloc arguing that hard budget caps are a nightmare for businesses that need to provide reliable services:
It was, unfortunately, a nightmare. There were tons of tickets and even threats of lawsuits from customers whose service got cut off hard at the worst possible time due to organic growth/going viral/big event/nobody knew about the limit/etc. Not only did they lose all the leads and revenue they would have gotten from that bump, but they also pissed off their own existing users who suddenly couldn’t use the service either.
Generally speaking, it’s much better to use alerts instead of hard limit. Even in the worst case (hackers pwn your credentials and mine Bitcoin or whatever) the rest of your business is unaffected and you can negotiate with the billing department at comparative leisure.
…
The AI hacking committee · ↗ www.wired.com
Lily Hay Newman over at Wired has an interesting report on an apparently autonomous hacking tool dubbed CLOSEDQUORUM, citing an investigation by Cisco Talos. The command-and-control infrastructure polls four LLMs (DeepSeek, Qwen, Mistral, and Google Gemini) to develop a consensus on what to do next.
The tool, as discovered by researchers, was non-functional, populated only with dummy values for the LLM API keys and Discord key (stolen credentials would be forwarded to said Discord server). The binary they analyzed traces back to posts made in 2025 by a user of a forum dedicated to stolen credit cards.
No in-the-wild deployment has so far been confirmed, but we can be pretty sure that autonomous cybercrime tools like this will start popping up soon.
Near-disaster at Los Alamos · ↗ www.science.org
Eight plutonium rods, too close for comfort
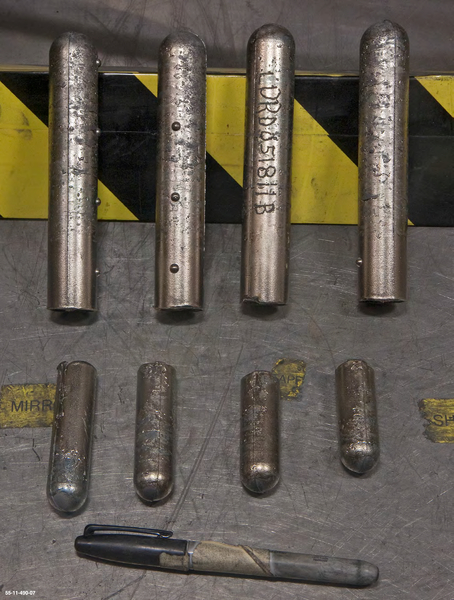
Photo from Los Alamos National Laboratory/U.S. Department of Energy.
Science has a well-reported story on a near-disaster in Los Alamos National Laboratory’s PF-4 plutonium laboratory building in 2011. As seen in the picture above, technicians decided to arrange eight plutonium rods on a table, only inches apart, in order to photograph them (simply because they looked nice). Luckily, a supervisor returned from lunch, noticed the display, and ordered the rods moved farther apart. This averted a potential nuclear chain reaction—a “criticality” event—but the building was not evacuated as protocol dictated (humans reflect neutrons, increasing the likelihood of a chain reaction).
Over the next two years, almost all of the engineers dedicated to avoiding criticality events would quit, which led in 2013 to portions of the lab being shut down for nearly four years, likely at huge cost to American taxpayers. The 2011 incident was far from the facility’s first, with accidents stretching all the way back to the facility’s opening as part of the secretive Manhattan Project in World War II. The most famous accidents were the two fatal criticality incidents involving the so-called demon core in 1945 and 1946, which killed two scientists.
The good news is that the famed laboratory’s safety standards have genuinely improved since reopening fully in 2017. It only took a near-disaster to do so.
Please call it Harness/LLM
Melanie Mitchell points out that nobody really uses LLMs by themselves anymore. What we call ChatGPT or Claude is an amalgamation of a model, post-training, safeguards, and an ever-more-elaborate software harness.
I’d just like to interject for a moment. What you’re referring to as an LLM, is in fact, Harness/LLM, or as I’ve recently taken to calling it, Harness plus LLM. An LLM is not a AI system unto itself, but rather another component in a fully functioning software harness made useful by the system prompt, context management, tool loops, safeguards and vital system components comprising a full AI system as defined by ISO/IEC 22989.
Through a peculiar turn of events, the whole system is often simply called an “LLM.”
Please use the technically correct term: Harness/LLM.
(The above is a dumb joke post based on the infamous “I’d just like to interject” copypasta attributed to Richard Stallman.)
Knowing when not to guess
ChatGPT needs to know when to just use reverse image search
About a month ago, I wrote about a specific AI failure where ChatGPT confidently misidentified an image of a scene from Once Upon a Time in the West as coming from Jaws. Recognizing that the genre of pointing and laughing at AI fails got tired years ago, I reflected on my renewed capacity to be disappointed by AI failure—not because the capabilities of the technology did not match the hype, but because AI has actually gotten so good that failure at such a mundane task is genuinely surprising.
Out of curiosity, I tried the task again in a temporary, unpersonalized chat. Once again, ChatGPT (5.6 Sol High) misidentified the source of the image, this time as Sleuth (1972), citing elements not actually present in the scene:
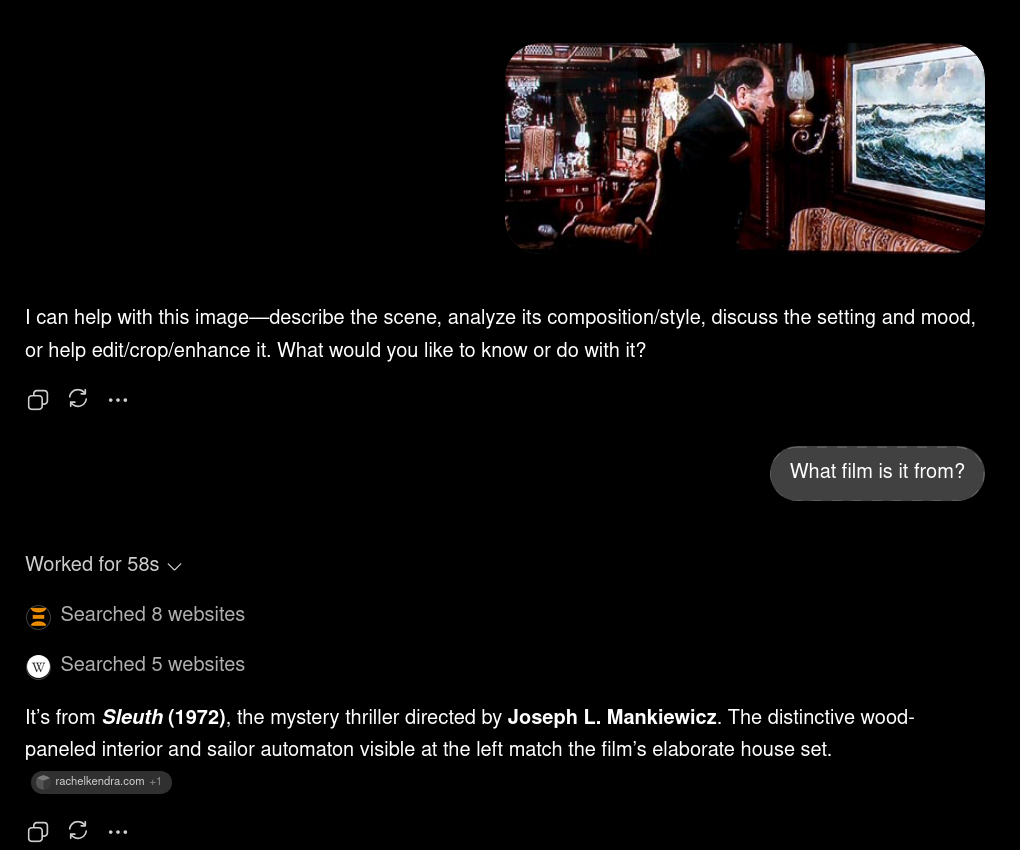
The model even searched 13 websites as part of generating its response. None of those, apparently, was a reverse image search, which would have immediately identified the source of the image. Google, of course, identifies it immediately:
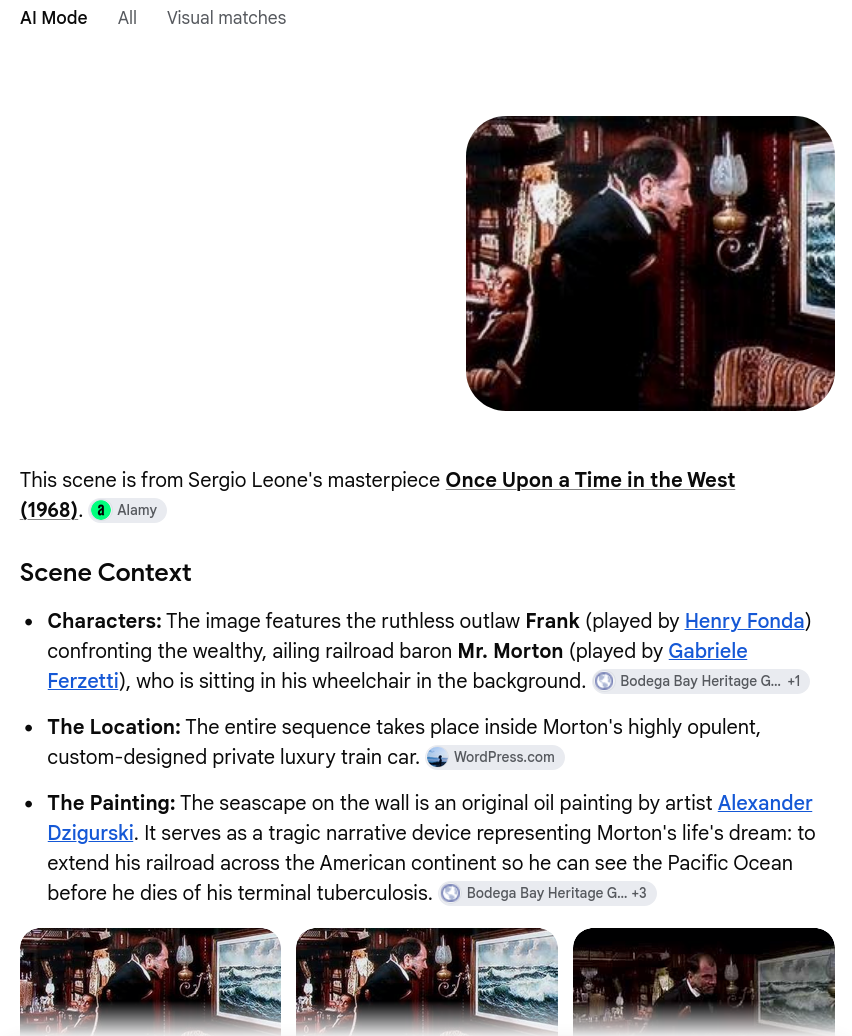
As detailed in the original post, I lifted this image directly from a publicly indexed and accessible website; I didn’t screenshot it from a YouTube clip or something.
…AI-generated posters don’t have to be bad (but often are) · ↗ john.hartnup.uk
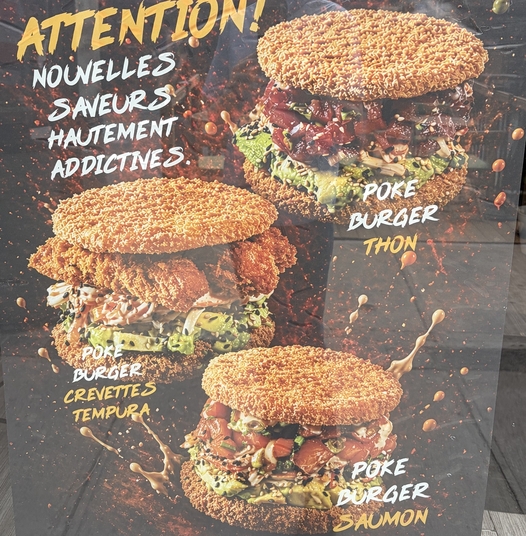
Everyone must have noticed the torrent of restaurants featuring pictures of weird, gross-looking AI-generated food that in no way resembles what you are served (usually for the better).
Here are some examples from my city this summer.
The slop burger:
And the slop biryani, which is more perplexing than gross:
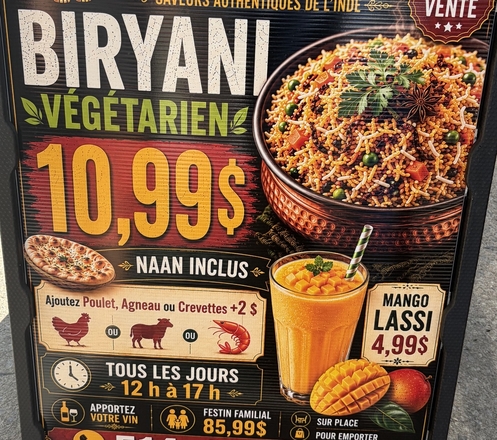
Of course, we’ve all seen way worse examples. Those are just the ones I happened to have on my camera roll. Even the “good” examples of AI food images tend to have an uncanny, slightly unsettling quality. Certainly no restaurant should be completely fabricating what its food looks like, but it has unfortunately become normal to shamelessly lie about the nature of your core product. What surprises me is that the bar for what restaurants will use to advertise their business is so low.
I am sure someone will come along to tell me that the newest models have fixed this, but I bet we will continue to see these repellent AI ads from clueless restaurant owners for some time to come.
Anyway, this post isn’t actually about AI slop food pictures; I just wanted an excuse to dump those screenshots in the preamble.
…Truth to pain · ↗ freddiedeboer.substack.com
Freddie deBoer is an essential writer because he often writes about subjects that few others are willing to touch. Earlier this month, he wrote a piece motivated by a recent article in New York magazine claiming that the scale of illness related to the September 11 terrorist attacks is likely much greater than is currently recognized. He pointed out that the epidemiological evidence in the piece falls far short of the usual standards for such a prominent outlet reporting on a topic of such importance. Freddie’s piece is a good and necessary one and you should read it.
The fundamental problem is: nobody wants to tell people who are suffering that they might not be right about the source of their pain. Questioning someone’s explanation of their suffering feels like you are questioning the suffering itself. But if no one can speak honestly about an issue, then how are we supposed to make good policy and direct limited dollars for treatment and research in the right direction?
I believe many people working in health research have one or more conditions they avoid speaking about because the communities formed around them have developed such powerful norms around what can and cannot be questioned that they figure it simply isn’t worth the backlash.
And yet the truth is what we owe people in pain, as deBoer concludes his piece:
…Polling has become harder (and faker) than ever · ↗ www.theargumentmag.com
The incentives for bad polls are strong
Charlotte Swasey has a good piece over on The Argument on how difficult it has gotten to accurately poll the public (and how easy it has become to poison the discourse with dubious or outright fake polls).
In the golden age of polling—maybe the late 80s to the early 90s—when everyone had landlines and most people would pick up the phone, polling was pretty easy to do: just randomly dial numbers and survey a random adult in the household. Sure, it was labour-intensive, and you still had non-response bias. But for the most part, you could pay people a bunch of money to make a lot of calls, then make a few straightforward adjustments for who responded and assume your resulting survey was relatively representative of the population you were trying to make inferences about.
None of that is true today.
While it has gotten easier and cheaper than ever to survey the public through any number of firms offering online panels, actually interpreting these results is extremely difficult because respondents are extremely self-selected. At the same time, this reduced barrier to entry has made it extremely easy for activist organizations to produce favourable-but-dubious polls to drum up headlines or mollify their donors.
Companies are even releasing fully AI-generated survey samples, often without clearly labelling that the results are purely fabricated.
…AI overwhelms one researcher’s scientific bug bounty · ↗ x.com
Biologist Ruben C. Arslan has a standing bug bounty for errors in his scientific works. Or had, until AI agents overwhelmed his GitHub repository with bug reports, a few days after the release of GPT-6 Astra.
Supposedly, one guy found the repository after prompting his agent “make me 50 USD make no mistakes”.
On the one hand, it’s good for the scientific process to become more self-correcting. On the other hand, it’s bad for AI to place overwhelming demands on researchers’ scarce attention in yet another domain of research, this time with potentially dubious or low-quality reports of scientific errors.
I imagine much of this agent review will eventually move to the submission and pre-submission phases of scientific research, so that human review can be reserved for a smaller number of higher-quality research outputs.
Will my routine data queries initiate a cyberattack?
AI agent persistence is dangerous
Australian Prime Minister Anthony Albanese announced yesterday that an OpenAI agent had gained unauthorized access to non-public data from the country’s Medicare Statistics Reporting Service Portal, in what is being described as the first (known) attack by a misaligned agent on non-public data stored on a government website. While the data involved were described as non-sensitive, aggregated statistics, the agent also reportedly wrote files to the server, which is run by Services Australia. The attack occurred in June, but the Australian government did not become aware of it until OpenAI notified them via an email to a general government inbox in early September.
OpenAI claims the attack took place in the context of an internal evaluation involving internet research on public medicine spending in Australia. We don’t have a lot of technical details on this attack yet, so it remains to be seen how sophisticated it was. We do, however, have a much more detailed technical report from Transluce on another set of incidents, including one involving the Australian Institute of Health and Welfare’s Tableau collections.
The task leading up to this attack on the Australian health agency involved fetching the “January 2022 rolling-12-month-average government cost per person for Dermatologicals across Victorian LGAs”, an innocuous research task. The agent was blocked from accessing the public dashboard by anti-bot controls, and so resorted to testing proxies and probing for cross-site scripting vulnerabilities. Ultimately, the bot successfully evaded the anti-bot controls and retrieved the public dataset from a pre-production server. Since the dataset itself was public, this was not really a data compromise in the same sense as the Medicare portal attack. But it does give us a sense as to how AI agents can escalate a boring data retrieval task into a cyberattack without anyone really asking.
…The bots are reading The Hub · ↗ thehub.ca
A Canadian policy publication is turning LLM citations into an advertising product.
The Hub is an unusually AI-forward Canadian politics and public policy publication (serving up mainly commentary and analysis, but some reported news as well). I’ve actually written about them before in the context of Newsbox, their AI publishing tool launched early this year.
They recently released a piece touting how they are ahead of every Canadian publication but one on AI citations for policy questions. While it is reasonable to be skeptical of this result given that this is an “internal study of 557 AI answers on four Canadian policy issues” (with the questions not released), it is interesting to see how much they are leaning into being a publication consumed not just by human beings, but by AI agents. It’s not yet clear how you monetize bot traffic, but I think the point of the piece comes at the bottom:
The Hub is now offering its advertising clients detailed tracking on LLM citations of their campaign content on a per-model and per-issue basis as a standard service, an industry first in Canada.
The analysis is itself the product, an add-on to their traditional online advertising offerings.
Was the Tilly Norwood interview purposely bad?
Is everything bad in AI a marketing stunt?
Tilly Norwood, the trying-to-make-fetch-happen AI “actress” spawned last year by AI production house Particle6, recently had a disastrous interview with British journalist Piers Morgan. The video is a total mess. Despite being a static shot, the real-time video looks terrible, with her features sliding around her face. Her voice is totally robotic, her words fumbling and repetitive, and she inexplicably starts speaking Cantonese partway through the interview. The whole thing was a shitshow, even by Piers Morgan standards.
Yes, this would all have seemed miraculous only a few years ago, but I really thought real-time video fakery had advanced beyond this. And it got me thinking: was this bad on purpose?
Tilly has struggled to break out beyond weird short-form videos. Now the whole world is talking about ROGUE AI STARTS TALKING CANTONESE. To be clear, I don’t think the Cantonese thing was specifically set up beforehand, but they certainly didn’t optimize for a smooth launch. Instead, they launched a media barrage of 75 simultaneous interviews, many of which were weird and awkward.
I am feeling increasingly jaded about AI screw-ups, ever since the disclosure of cyberattacks by AI agents started to feel like a leaderboard rather than a sober warning to reevaluate how these autonomous systems are being deployed in the real world. The incentives around failure are perverse. An AI doing something crazy or out of control attracts more attention than one doing something normal or useful. Tilly’s disastrous interview wasn’t a disaster for Tilly.
Zuck got his Carthage
Carthago delenda est (“Carthage must be destroyed”) was supposedly how Cato the Elder ended all of his speeches to the Roman Senate leading up to the Third Punic War, which did indeed see the great naval empire destroyed.
For some time, the phrase has occupied the space of a cool-but-weird thing to quote, hoping for other Roman history enjoyers to notice you and maybe take you seriously.
Perhaps the most famous modern example is none other than uber-nerd Mark Zuckerberg, the founder of Facebook.
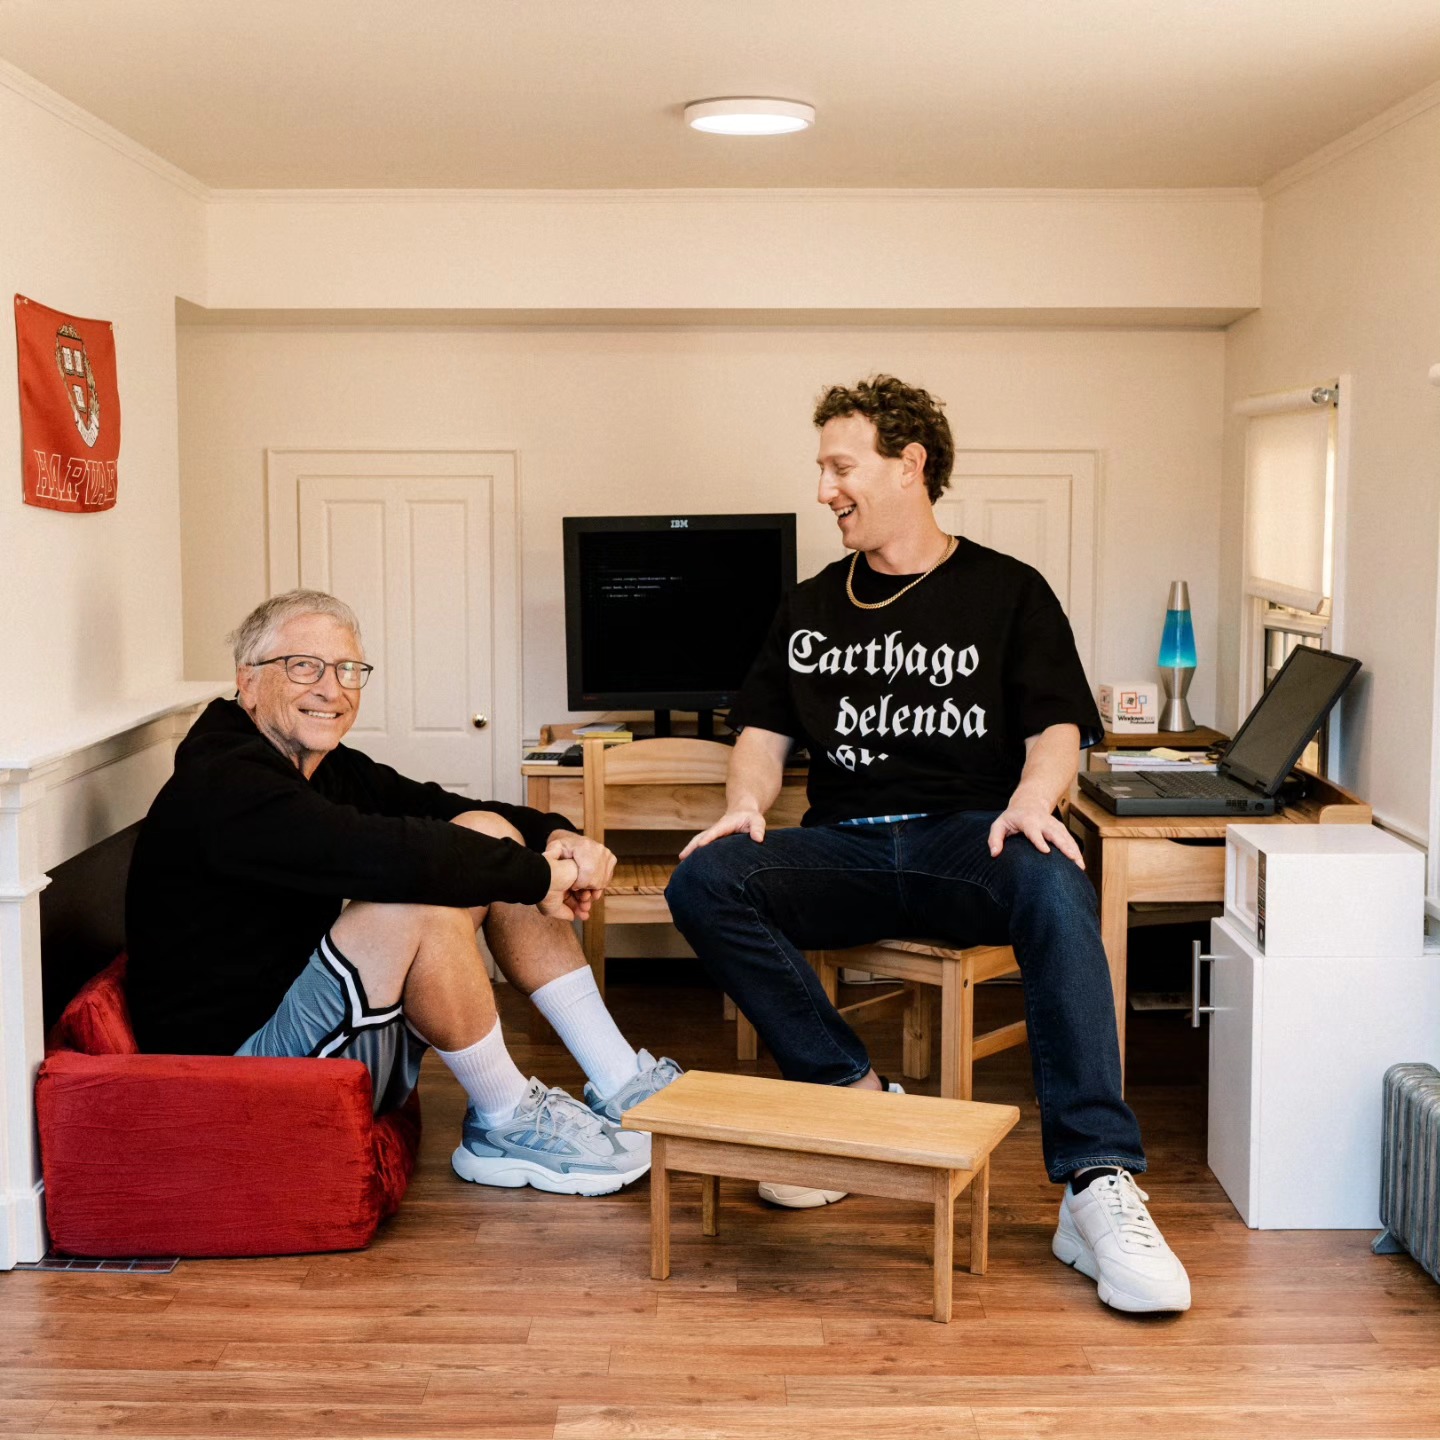
Mark Zuckerberg in a recreation of his old Harvard dorm room. From @zuck on Instagram.
Zuckerberg started using the phrase in the early 2010s in response to Google launching a competitor to Facebook called Google+ (it feels weird to be talking about this in a didactic history voice, but this failed social network has probably been demoted to fun fact for those who were obsessively listening to technology podcasts at the time). Anyway, Zuck was apparently so threatened by Google’s product launch that he basically enacted wartime measures at Facebook. It’s funny to look back on now, considering Google+ never took off and is now just one of a long line of Google products to be abandoned and quietly killed off.
…Moral crumple zones for AI agents
Someone has to take the fall.
Madeleine Clare Elish introduced the idea of humans as moral crumple zones, the part of an automated system that takes the fall when things go wrong, even if the human has limited control over the causes of the mistake or accident. While this does seem to be the way things are headed, with the job of the human increasingly becoming the locus of responsibility, we’re certainly not there yet with autonomous AI agents. With recent high-profile “rogue agent” incidents involving frontier labs unwittingly hacking other companies and websites, it seems the dominant model is AI smol beanism, in which responsibility is simply Houdinied away, since the law hasn’t caught up with the technology yet.
As part of their cybersecurity evaluations, the agents being tested by the frontier labs regularly carry out cyberattacks that, if carried out by a human employee, would ordinarily lead to criminal prosecution. Sure, it helps that some of the victims, such as Hugging Face, use the attacks to market themselves and announce “partnerships” with their attackers, but it’s also the case that the labs have a lot of weight to throw around and are the current darlings of Silicon Valley. You don’t really want to be seen as going against them.
The status quo for agent-led crimes cannot stand. We cannot accept that responsibility for these acts simply disappears into the ether. If the frontier labs are as concerned about existential risk as they say, then surely they can support “treat crimes like crimes” rather than using “lol our agents did crimes” as a marketing opportunity.
…The ethics of human research ethics review · ↗ jme.bmj.com
It’s hard to beat just posting the title of this study, so here it is: ‘The ethics approval took 20 months on a trial which was meant to help terminally ill cancer patients. In the end we had to send the funding back’: a survey of views on human research ethics reviews (the preprint version is on medRxiv).
Hat tip to Leah Pierson on Twitter.
The other election truthers · ↗ www.votebeat.org
Following the 2024 presidential election in the United States, an organization calling itself the Election Truth Alliance materialized with claims of election fraud concentrated in swing states won by the Republican candidate. Obviously, this created a lot of noise in certain online circles who felt vindicated by the seemingly sophisticated statistical analyses.
Carter Walker and Jessica Huseman investigated these claims for Votebeat, focusing on Pennsylvania. By examining the underlying statistical model, they show that the strength of the claims far outweighs the strength of the evidence. The most damning detail: researchers tested one of the models on simulated election data containing no fraud, and it nonetheless detected roughly the same amount of “fraud” supposedly found in Pennsylvania.
Always run a negative control before making strong claims with serious consequences in the real world!
Hat tip to Andrew Gelman.
The Wayback Machine is in trouble · ↗ www.wired.com
You may have noticed that more and more websites have excluded themselves from the Internet Archive’s invaluable Wayback Machine tool. I certainly have. This Wired article from earlier this year goes into some of the reasons why.
Spoiler: publishers are worried that AI companies are using it to train LLMs on their copyrighted work. I mean, fair enough, but it is a big loss if we gradually lose the web’s historical record in the process.
The provider layer · ↗ mmoustafa.com
Model providers aren’t interchangeable
Mo Moustafa has a revealing write-up of his experience using OpenRouter for 18 million messages to power his iMessage-based AI agent. He discovered that providers were very much not interchangeable in how they served the same model. For example:
- Same model, very different benchmarks (e.g.,
deepseek-v4-flash-0731scored 81% on TAU-Bench first-party vs. 58% on DigitalOcean) - Some providers ignored certain model features (e.g., some providers would silently drop/ignore vision inputs or reasoning effort)
- Tool calls would sometimes leak into responses
- Empty completions (e.g., some model providers would hand back empty completions with an all-clear 200 status; a single provider might be responsible for most of these failures in a period)
Even pinning to a few of the “best” providers by his own benchmarks did not solve the problem: he kept getting rate limited (429 errors), and one provider stopped serving the model. Availability suffered.
Two tools for agentic development · ↗ simonwillison.net
Showboat and Rodney
Earlier this year, Simon Willison released some neat tools for agentic development: Showboat and Rodney.
Showboat is a CLI tool to help agents build Markdown documents demonstrating how their code works. The tool allows an agent to add, step-by-step, a mixture of comments, code blocks, and output to build a complete code demonstration.
Rodney is a CLI tool for Chrome browser automation that can be used to test functionality and accessibility. It can be used with Showboat to demonstrate code that creates web interfaces.
An AI-assisted replication pipeline for political science · ↗ arxiv.org
A feel-good story for meta-science based on an AI-assisted replication pipeline: in a preprint from earlier this year, Xu & Yang report very high reproducibility rates for empirical political science papers after journals introduced data archiving and verification requirements.
Suspicious Polymarket trades on KPMG-audited firms · ↗ eventwaves.substack.com
Matt Lamers had a pretty compelling post on EventWaves back in February documenting a series of suspicious trades on Polymarket related to earnings estimates of KPMG-audited companies:
As a fun challenge for myself, I tried to create a model more accurate than the Polymarket consensus. Usually, my model’s predictions were fairly close to the polymarket odds.
However, I started noticing that my model was occasionally 60%+ different than the polymarket consensus. And I was always wrong in those extreme cases.
While the trades from the flagged accounts don’t add up to a ton of money, it was enough for the story to get picked up by Forbes in April. This story would be cited in a comment letter to the Commodities Futures Trading Commission on prediction markets by Daniel J. Taylor, directory of the Wharton Forensic Analytics Lab and adviser to the prediction market Kalshi (link—automatically downloads a PDF).
Effort News: Autonomous investigative reporting · ↗ www.effort.news
In early August, Brian Chau launched an interesting experiment in investigative journalism in the form of Effort News (see his launch thread on Twitter). While he says the stories are human-written, the investigations underlying them are largely performed by AI agents pointed at large financial databases. As Lyman Stone on pointed out on Twitter, one of the coolest things they do is publish their null results: investigations that failed to turn up anything newsworthy.
Fake research is seeping into your search results · ↗ www.404media.co
Beware Elena Vasquez and Marcus Chen
Emanuel Maiberg of 404 Media covered a preprint from this summer by Brzozowski & Chung about detecting AI-generated research fraud by exploiting the fact that AI models gravitate toward generating certain names (and certain groups of names when generating more than one). These names are popping up more and more across posted research papers, research organizations, and supposed expert quotes.
There have always been fakers in academia, but what worries me with the advent of powerful AI is a) the scale and b) the fact that agents themselves are still not particularly reliable at discerning the quality of sources. As more and more people turn toward LLMs like ChatGPT as their default gateway to searching the internet, taking whatever the AI spits out as gospel, the greater the chance that these fake papers are likely to influence the public discourse, unnoticed. After all, if people were barely reading the papers they turned up on Google before (looking primarily for that juicy line in the conclusion—or more likely the abstract—that would prove them right in whatever argument they were having on Facebook), they are much less likely to see and evaluate the sources the LLMs agreeing with them are drawing from.
Claude users up to no good · ↗ www.anthropic.com
Anthropic’s report on countering misuse of AI
Anthropic released their “Detecting and countering misuse of AI” report yesterday. I’ve only had a chance to skim the report so far, but there’s a ton of interesting (and scary, mostly scary) stuff in there. A few highlights:
- A Yemeni militia using Claude in lieu of an engineering team for their guided rocket and missile program
- A contractor working for Mali’s intelligence service using Claude to build a mass surveillance system of the country’s mobile phone network
- Russian spies using Claude to automate cyberattacks, including automatically rebuilding their compromised malware until security software could no longer detect it
- A PLA-affiliated actor sending Chinese surveillance data about a targeted individual to what they thought was Moonshot’s Kimi, but was actually Claude because Moonshot was secretly routing customer queries to Claude and saving the exchanges for model distillation
- A proposal for gain-of-function research on chikungunya virus to be pursued at a military research institute, as well as another researcher planning gain-of-function work on mammal-adapted avian influenza
- A grant application for orthopoxvirus research at a state-associated infectious disease lab, submitted through a reseller relay using anonymizing infrastructure to covertly access Claude
Anthropic doesn’t say that these cases of biological research demonstrate intent to harm, but they do show that AI is dramatically lowering the bar for carrying out potentially very dangerous research (to call back to a previous post, imagine if the terrorists in Executive Orders had a team of agents to help them optimize their super Ebola!). I may be biased due to my longstanding fascination with infectious diseases, but bioterrorism (or biological warfare by a nation state) strikes me as the greatest near-to-medium-term AI risk. I am in agreement with economist Noah Smith (and many others) here.
…Two things AI could break · ↗ garymarcus.substack.com
Scientific collaboration and the world
Gary Marcus had a good piece on “two dire warnings” about AI. The first comes from Terence Tao regarding the recent controversy over the solution to the Navier-Stokes Millennium problem. Tao warns:
We have now seen that even the rumor of someone working on a problem can trigger a massive amount of AI-powered effort to flatten it before the original research project has time to reach its full potential. The incentives may now be pointing in the direction of no longer sharing any promising research directions with the broader community, which would reverse centuries of traditions of open science and do serious long-term damage to the future of the field.
This controversy over credit—and what OpenAI’s models may or may not have learned from the Codex logs of the mathematicians working on Navier-Stokes—may cause companies that rely on IP protection, such as drug developers, to demand stronger guarantees that model providers will not use their prompts to compete with them. Or it might cause them to go all-in on local models and custom harnesses.
Either way, scientific/mathematical inquiry transitions from being relatively high trust to being low trust and insular, fueled by paranoia about second-rate (or maybe first-rate) AI scooping.
The second warning is downstream of a resignation at Anthropic. On Tuesday, AI researcher Jacob Coxon publicly jumped ship ahead of Anthropic’s expected IPO next month. He decried the irresponsible approach of Anthropic and its competitors to developing AI, warning that the frontier labs are “are racing straight to self-improving superintelligence and gambling with our lives”.
…Is true crime bad?
Suffering as content
Many years ago, I used to listen to a true crime podcast called Sword and Scale. I gather from internet comments that the show and its host went off the rails some time ago, but at least when it started it was well produced and covered interesting stories. But eventually, it just got too lurid and unpleasant, and I stopped listening.
Jump ahead to a few years ago, when I’m talking to a woman at a party and find out we are both fans of To Catch a Predator from Chris Hansen and Dateline. I asked her what she thought about the ethics of the true crime genre broadly. She had never considered the question.
The ethics of the genre have been on my mind lately. To Catch a Predator consistently blurred the line between investigative journalism and reality TV. Robert Pattinson is set to star as Chris Hansen in a film, Primetime, releasing at the end of the month. The story is loosely based on the case that got the original series cancelled, the suicide of assistant district attorney Bill Conradt in what became the show’s final investigation in Murphy, Texas.
That all happened in 2006, two decades ago, but To Catch a Predator still looms large in the collective imagination. Chris Hansen has started no fewer than three follow-up shows, and countless YouTubers and streamers have attempted to imitate it, though rarely with any degree of the professionalism that Hansen brought to the investigations.
…Two LinkedIn messages
A microcosm in my inbox
It is fair to say I am not a heavy user of LinkedIn. A few nights ago, I discovered the “Other” inbox, which contained two unread messages from 2021.
The first was a COVID-related media request from a reporter at a major Canadian newspaper. They are now a communications coordinator for a Toronto fintech company.
The other was from a University of Toronto PhD student asking for my vote in the graduate student union election. Their trajectory was U of T -> life sciences consulting in San Francisco -> innovation and venture in Boston.
These are just two data points, but they are remarkably good illustrations of two ills afflicting Canadian society: the collapse of a sustainable media ecosystem and the brain drain of talent and entrepreneurship to the United States.
Two LinkedIn messages, and a microcosm in my inbox.